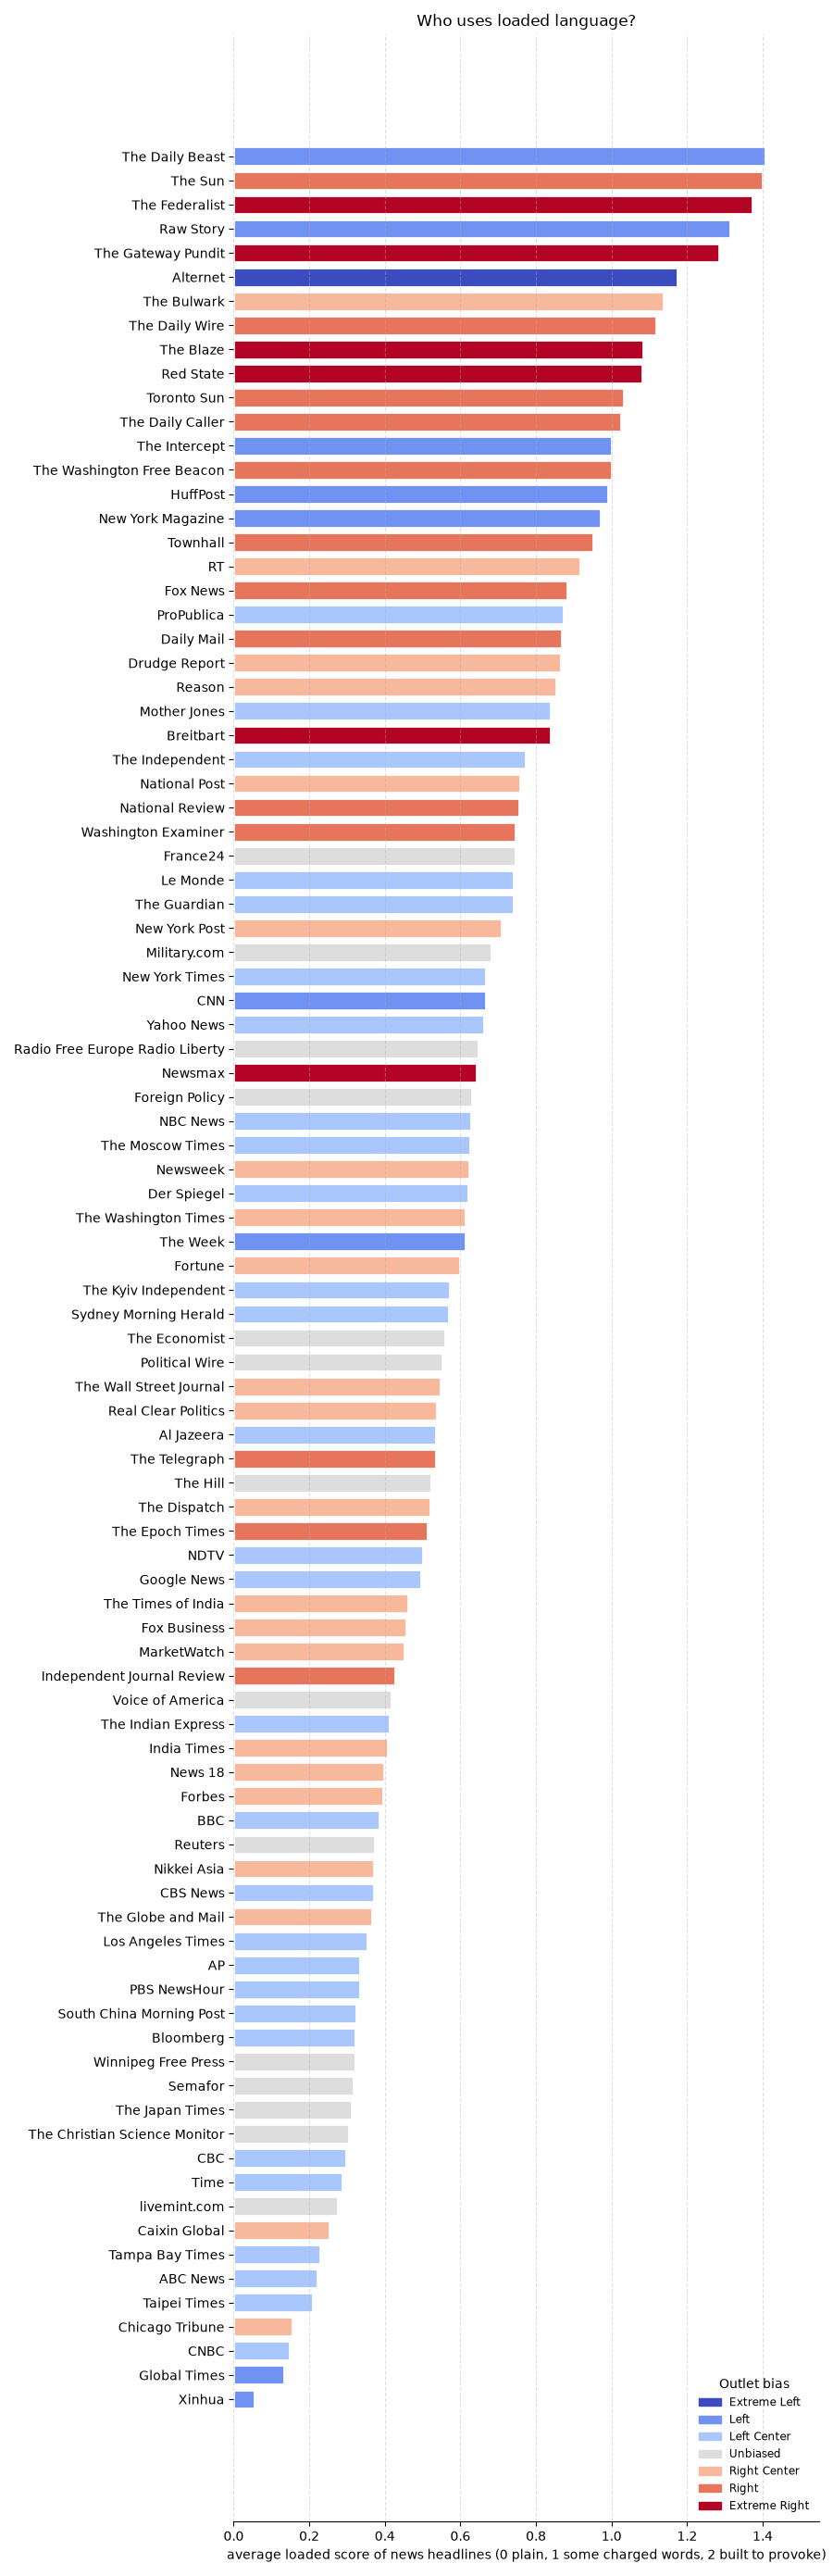
Loaded language
A local language model scores how much each headline's own wording adds emotion, judgment or alarm beyond the facts: 0 for plain wording, 1 for a charged word or two ("slams", "chaos"), 2 for headlines built to provoke. Words quoted from a source don't count. Averaged over each outlet's news headlines from the last 30 days; outlets need 30 or more to appear.
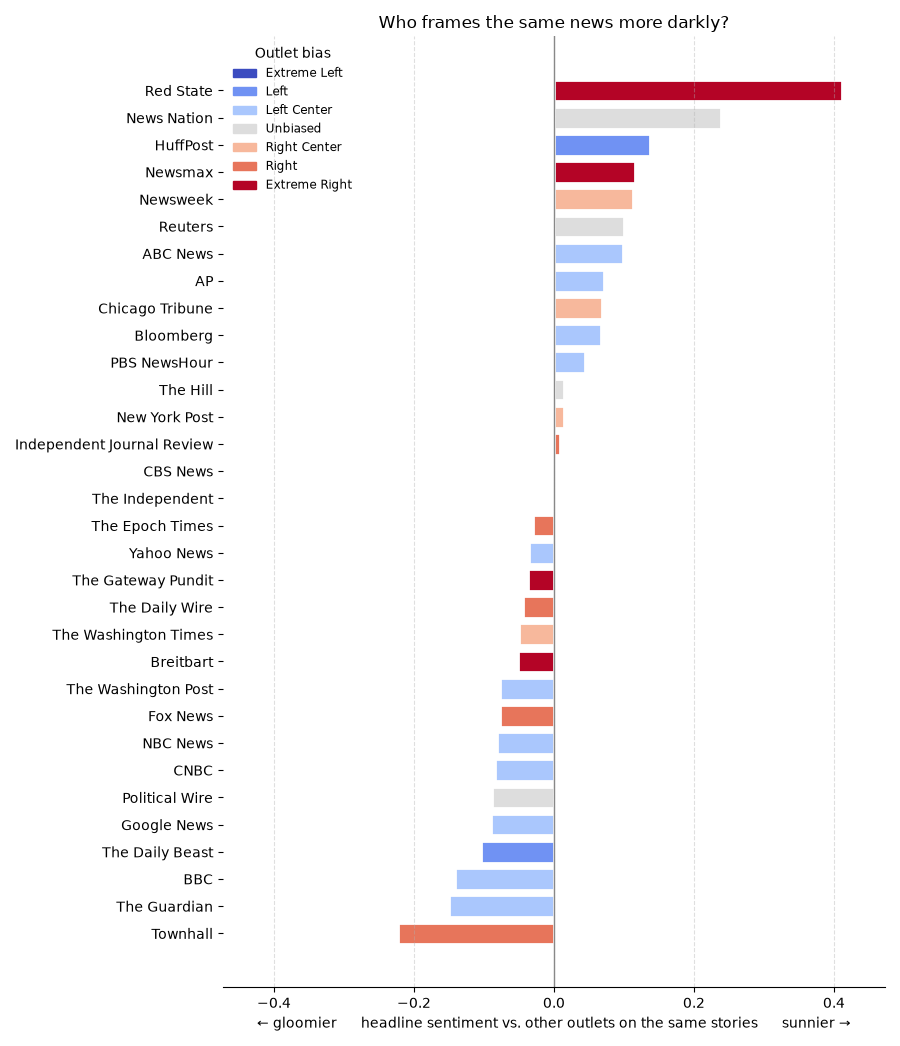
Framing
For every story covered by at least six outlets, a local language model scores how good or bad each headline makes the event look, and that is compared with the average across all outlets covering the same story. Averaged over the last 30 days, this separates how an outlet frames the news from which news happens to be bad. Outlets need five or more stories to appear.
These metrics exclude non-US media sources.
VADER and AFINN are sentiment lexicons.
(-left/+right)
(-left/+right)
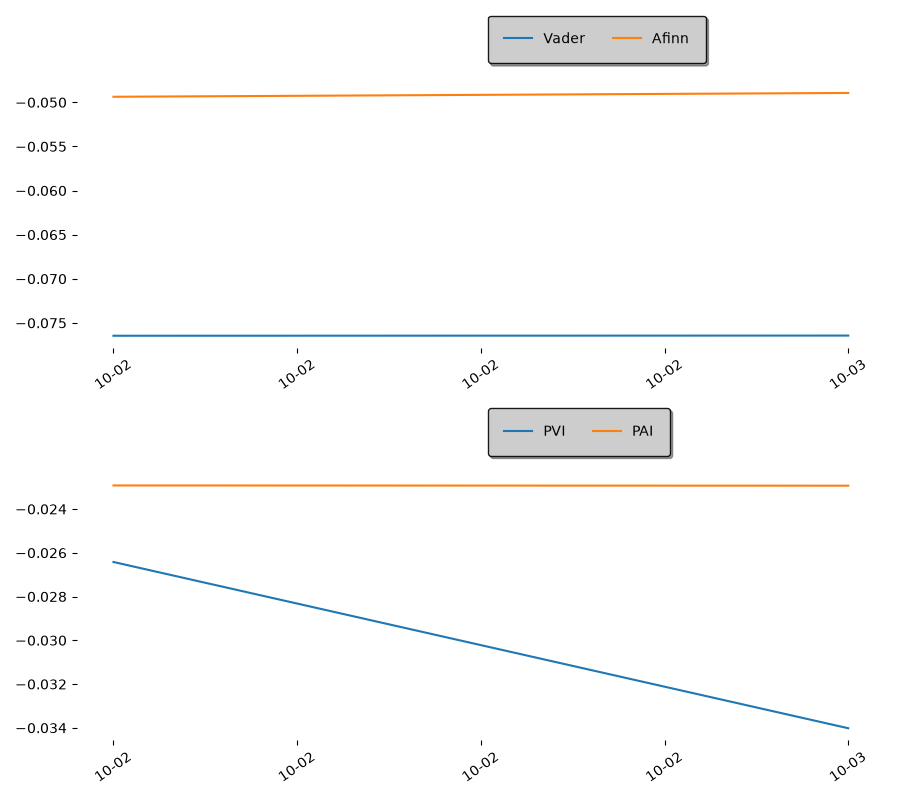
The below sentiment values only include currently displayed stories.
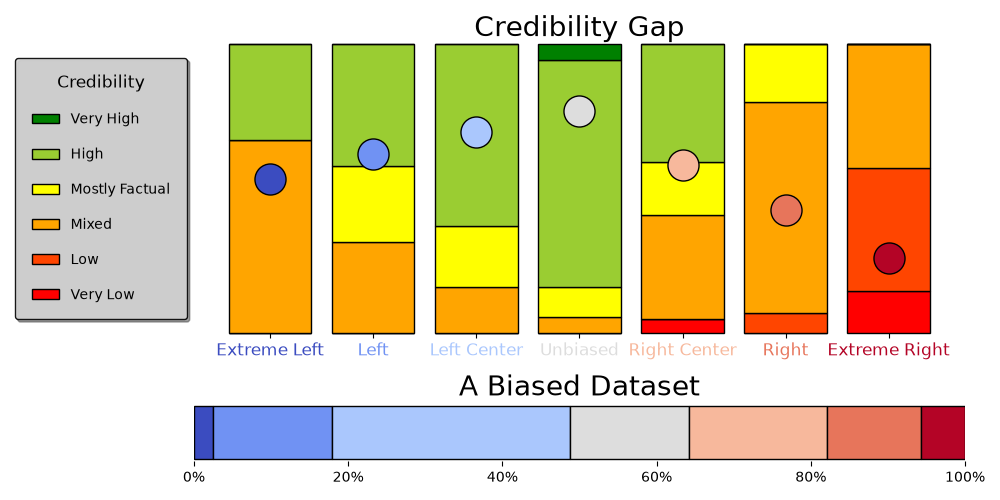
Updated at 2026-10-03 11:00:35 EST (GMT-5). Updates are every 30 minutes.All bias and credibility ratings are taken from Media Bias/Fact Check